Many problems arising in mathematical modeling and machine learning can be casted as an optimization problem, i.e.,
where is a function with adequate “regularity” defined on a space , the domain of the problem and is a space where the notion of infimum is well-defined, such as .
Depending on the context, we may be interested in proving the existence of a minimizer, i.e., a point that achieves this infimum.
In this case, we say that is the minimum of the function over .
1.1 Examples of optimization problem
This previous definition is quite vague.
It requires some precisions, and to do so, we instantiate it on several important examples.
Toy examples
It is common in optimization to test algorithms on function from to for the single reason that it is easy to visualize their behavior using contour plots, and that their geometry are rich enough in comparaison to the univariate case.
Figure 1 illustrates two functions:
The Rosenbrock function, also known as the “banana function”, is a function commonly used in optimization.
It was first introduced by Rosenbrock (1960) as a way to test the performance of optimization algorithms.
A typical value is .
Note that for , the global minimizer is unique.
If , every is a minimizer; if , the function is unbounded below.
A (positive) quadratic form, defined as
Rosenbrock function
Quadratic function
Move the point on either plot, or adjust the sliders. The minimizer is marked ×.
Figure 1.Contour plots of functions from to . (Left) Rosenbrock function. (Right) Quadratic form.
Ordinary Least Squares
One of the fundamental model in statistics is the ordinary least squares (OLS) problem.
Given a matrix and a vector , the OLS problem seeks a vector that minimizes the sum of squared residues:
where denotes the Euclidean norm.
This formulation arises naturally in linear regression, where represents the data matrix (with each row corresponding to an observation and each column to a feature), and is the vector of observed responses, typically modeled as , where is unknown and represents noise or model error.
The identity is the noiseless special case.
The solution to the OLS problem, when has full column rank, is given by the unique minimizer
If does not have full rank, the set of minimizers is generally infinite, and the minimum-norm solution can be found using the Moore-Penrose pseudoinverse:
(Empirical) Risk minimization
Given a function , a loss function and a probability measure on , the expected risk of the prediction is defined as
Minimizing expected risk over a chosen class leads to the optimization problem
Here is a class of measurable predictors, and the loss is assumed measurable with well-defined expected risks, for example a nonnegative measurable loss.
A minimizer, if it exists, is optimal within .
A Bayes predictor minimizes expected risk over all admissible measurable predictors; a restricted class need not contain one.
Under the assumptions stated here, the infimum need not be attained.
In practice, in supervised learning, we don’t have the knowledge of the distribution but only to a training data .
The empirical risk is defined as
Of particular interest is the structural risk minimization – a term that trace back to Vapnik & Chervonenkis (1974) – where in additional to the loss function, we consider a regularization function that represents an apriori, and an hyperparameter and we seek to solve the minimization problem
Consider economic assets whose returns are denoted .
We assume to know the expected returns generated and the risk in/between the assets defined by the covariance matrix (assumed to be positive definite).
The problem of portfolio optimization with minimal variance and expected return is to find a
The foundational paper on modern portfolio theory was written by Markowitz (1952).
Optimal control
Given a dynamical system drive by the ordinary differential equation
where
is an interval of , open, open;
are the initial conditions;
is .
For the remainder of this example, take and let be an open interval containing .
Let consist of measurable controls such that, on every compact interval , the values of lie almost everywhere in some compact set .
In particular, these controls belong to .
The compact-range condition and give local integrable bounds and local Lipschitz bounds in the state variable.
Thus each has a unique maximal forward, locally absolutely continuous solution , satisfying the differential equation almost everywhere and the initial condition at .
For with , let be the controls in whose solution exists and remains in on .
Mere local boundedness in the ambient space, without suitable bounds inside , does not suffice for the preceding existence claim.
Given a cost function , assumed continuous so the cost integral is finite for each , the fixed-time optimal control problem is defined as
Besides its natural applications in engineering (including aerospatial), optimal control is at the heart of reinforcement learning.
For a comprehensive treatment of optimal control, see the lecture notes of Evans (1983) and for application to reinforcement learning, see (Recht, 2019).
Optimal transport
Let two metric spaces, a Borel measure on and a measurable map.
We recall that the push-forward of by is the measure defined by the change-of-variable formula
for all measurable and bounded .
For a given probability measures and , and a cost function , the Monge problem of optimal transportation is defined as
The optimization is over measurable maps and may be infinite-dimensional, but need not be when the spaces are finite.
For maps into a Euclidean space, the push-forward constraint is generally nonconvex, whereas convexity of the objective depends on the cost.
For arbitrary metric spaces, convexity of maps requires additional linear structure; these claims are not universal.
For more information, see (Villani, 2009) for theoretical and (Peyré & Cuturi, 2018) for computational applications (including machine learning).
1.2 Basic facts on optimization
Suppose we have an constrained minimization problem on as follows
Such problem may not have a solution.
For instance, if , then is not lower-bounded, and the infimum is .
But a function may be lower-bounded, for instance on , but the infimum is never achieved.
The following theorem shows that if is continuous, and that we consider a non-empty compact – that is bounded and closed – subset of , then the infimum is a minimum.
Theorem 1: + compact global minimizer
If is continuous and is non-empty compact, then there exists at least one global minima of on .
Proof
We recall that the Bolzano–Weierstrass theorem states that any bounded sequences of contains a convergent subsequence.
Let .
Consider a minimizing sequence of elements of such that converges towards .
Using the Bolzano–Weierstrass theorem, there exists a subsequence converging to some .
By continuity of , we have converges to .
Hence, , i.e., is a global minimum of on .
Unfortunately, this argument cannot work anymore for unconstrained minimization when .
The trick is to replace the compactness assumption on by the (0-)coercivity of , i.e.,
In this case, we have the following result
Theorem 2: + coercive global minimizer
If is continuous and coercive, then there exists at least one global minima of on .
Proof
Since is coercive, there exists such that
Consider the closed Euclidean ball .
Using Theorem 1, there exists a global minima of on :
In particular, , and in turns
that is is a global minima of on the whole space.
It is possible to generalize this result by asking merely that is lower semicontinuous.
These two results (Theorem 1 and Theorem 2) can be generalized in (infinite dimensional) Hilbert spaces with some additional hypotheses.
See the references for more insights in this setting.
Let us finish this section by introducing our usual suspect all through these lecture notes.
Example 3: Least-square minimization
Let and .
The quadratic loss is defined as .
It is always lower-bounded by 0 as the norm is a nonnegative function.
However, coercivity is verified if, and only if, its nullspace is reduced to the trivial vector space.
To see this, suppose that and consider a minimum of .
Then, for all , we have , hence the set of minimizers is unbounded.
Reciprocally, suppose that .
In particular, is injective, thus there exists some such that .
The reverse triangle inequality gives
Therefore , and hence , as .
We will see later that there is in fact only one minimizer in this case.
2 Basic facts in convex analysis
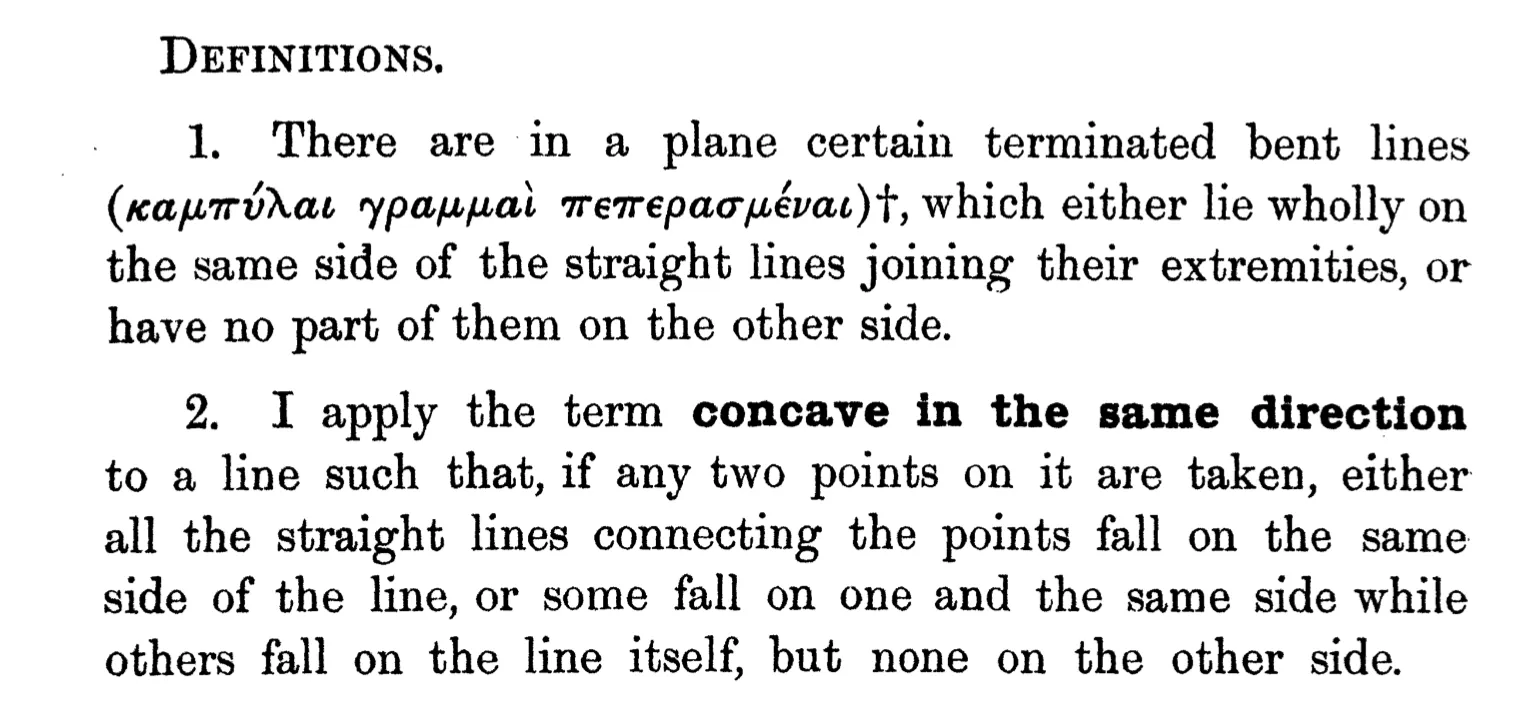
Figure 2.Definition of concavity by Archimedes
Despite the fact that many problems encountered in statistics and machine learning are not convex, convexity is an important to study in order to understand what is the generic behaviour of an optimization procedure.
2.1 Convex set
Convex set C
Nonconvex set D
Figure 3.Convex and non-convex sets. The set is convex whereas is nonconvex.
A set is convex if every segment of is contained in .
It can formalized as the following definition and illustrated in Figure 3.
Definition 4: Convex set
A set is convex if
One can observe that it is possible to replace by without any difference (see Exercise 1).
In most of these lecture notes, the set will the Euclidean space , but remark that this notion only requires that is a vector space over the real numbers , possibly of infinite dimension.
Example 5: Basic convex sets
We state several basic examples of convex sets.
The convex sets of are exactly the intervals of .
Any affine hyperplane where is a real vector space, a linear functional and is convex.
Any half-space is also convex.
The unit simplex of defined as
is convex.
The nonnegative orthant is convex.
The following proposition reviews some important algebraic properties of convex sets.
Proposition 6: Operations on convex sets
Arbitrary intersection.
Let convex sets where is a set.
Then is convex.
Cartesian product.
Let be sets of .
If every is convex, their Cartesian product is convex.
Conversely, if the product is convex and every factor is nonempty, then every is convex.
Without nonemptiness the converse fails, since a product with an empty factor is empty and therefore convex.
Sum.
Let , two convex sets.
Then the (Minkowski) sum is convex.
Affine map.
Let be an affine map and a convex set.
Then the image is convex.
2.2 Convex functions
Definition
The intuitive definition of a convex function is a function such that “the line joining and lies above the graph of between and ”.
Formally, this definition makes sense using the definition of the epigraph of .
Definition 7: Epigraph
Let and .
The epigraph of is the subset of defined by
(a) Nonconvex function
(b) Convex function
The shaded region is the epigraph. Move the endpoints to compare the graph with the chord.
Figure 4.Epigraph of a function.
Equipped with this notion, we can define convex functions using the definition of convex sets (Definition 4) applied to the epigraph (Definition 7).
Definition 8: Convex function
A function such that is convex iff its epigraph is convex.
It is possible to make explicit this definition as follow:
Following the convention introduced in (Hiriart-Urruty & Lemarechal, 1996), we will denote the set of all convex functions of as , and the set of closed – that is, with closed epigraph – convex functions of as .
Local and global minima of a convex function
For a (un)constrained minimization problem on a convex set with a function ,
we say that is
a local solution of (4), if there exists a neighborhood of such that for all , ;
a (global) solution if for all , .
A fundamental result is that every local solution of (4) is global solution, and the set of (global) solutions is a convex set.
Theorem 9: Local minima of convex functions are global
Assume that is a convex function and is a convex closed set.
Then,
1.
By contradiction.
Consider a local solution and assume that is not a global solution.
In particular, there exists such that .
By convexity,
Let be a neighborhood witnessing local minimality.
Since as , this point belongs to for sufficiently small .
The strict inequality above then contradicts local minimality.
2.
Take two global solutions, and study the segment joining it: let and two solutions.
We have , and in turn,
where the first inequality comes from global optimality of and feasibility of for , and the second by convexity.
Differentiable properties of a convex function
A differentiable function is convex if, and only if, it is above all its tangents, see Figure 5.
Proposition 10
Let be a differentiable function on an open set , and a convex subset of .
Then is convex on if, and only if,
Proof
Assume is convex on .
Let and .
By Definition 8, we have
Dividing by , and letting goes to 0, we obtain (5).
Reciprocally, let , and define .
Applying (5) twice, we have
Using a convex combination of these two lines, we get
(a) Convexity and differentiability. The curve y = f(x) is always above its tangent (dashed).
(b) Strong convexity and differentiability. There is space for a quadratic form between the curve y = f(x) and the tangent.
Figure 5.Convex and differentiable functions. Here .
A similar criterion can be derived for strictly convex function1.
For an unconstrained local minimizer in an open domain, , and (5) directly gives global optimality.
For minimization over a convex set , local minimality instead implies
by taking feasible one-sided derivatives along segments.
Together with (5), this also proves global optimality.
The gradient need not vanish at a constrained minimizer: for on , the minimizer is and .
2.3 Strongly convex functions
Throughout this section, denotes the Euclidean norm.
In particular, the equivalence with subtraction of and the Hessian criterion below use this norm.
A strongly convex function satisfies a stronger statement of the Jensen’s inequality.
Definition 11: Strongly convex function
A function is strongly convex of modulus if is convex and
for all and .
Another way to define strongly convex function is to say that is -strongly convex if the function
is a convex function.
A finite-valued strongly convex function has a unique minimizer.
More generally, the conclusion holds for a proper (never and finite at some point) lower semicontinuous strongly convex function.
Strong convexity alone does not imply attainment for an arbitrary extended-valued function; for example, on and otherwise has infimum but no minimizer.
For the finite-valued full-domain case, set .
This is finite-valued and convex, so it is continuous and has a supporting affine function at : for some , .
Consequently,
Thus is continuous and coercive, and Theorem 2 ensures existence.
Strong convexity implies strict convexity on the effective domain, so two distinct minimizers are impossible.
Strict convexity alone gives at most one minimizer, rather than existence.
For a differentiable function on a convex domain, strong convexity is equivalent to a uniform quadratic lower bound above every tangent, with the same modulus for all pairs of points, as in the following proposition.
At the point of tangency the bound is an equality.
This is a key property to defined lower bounds on .
Proposition 12
Let be a differentiable and -strongly convex function.
Then,
Note that if is , is -strongly convex if, and only if, its hessian .
An easy consequence is that it is possible to establish a lower bound on the values based on a lower bound on the distance between points:
where is the minimizer of .
2.4 Lipschitz continuity of the gradient
Definition 13: -smoothness
A differentiable function is said to be -smooth, with , if is -Lipschitz, i.e.
Here is the dual norm of .
Quadratic upper-bound
-smoothness is important in optimization because it ensures a quadratic upper bound of the function.
The last step is an equality: write with and .
Every admits this representation, and is represented by and any unit vector.
Allowing signed is equivalent to allowing both and .
Factorizing the trinom in leads to:
Hence,
By the definition of the dual norm, the maximum of over is , attained on the compact unit sphere.
In the Euclidean case with a nonzero gradient, one may take .
If the gradient is zero, any unit vector suffices.
Hence
which proves the left-hand inequality.
Co-coercivity of the gradient of a -smooth function
Convex -smooth functions are co-coercive.
This result is sometimes coined Baillon–Haddad theorem (Baillon & Haddad, 1977), but one shall note that the original contributionis much more general than its application to the gradient.
Proposition 16
Let be a full-domain convex -smooth function.
Then, is -co-coercive, i.e.,
Proof
Let and .
The two are convex.
Since is -smooth, and are also -smooth.
Canceling the gradient of shows that minimizes .
Hence, using the quadratic upper bound, we have
Doing exactly the same thing for leads a similar bound, and combining the two gives the result.
It turns out that smoothness, co-coercivity and upper quadratic boundness are equivalent properties for full-domain convex function.
Proposition 17
Let be a differentiable convex function with .
Then the three following properties are equivalent:
The implication is Proposition 14.
For , define and similarly .
Convexity ensures that minimizes and minimizes .
Both shifted functions inherit the upper bound (2), and the lower-bound argument in Proposition 15 uses only that upper bound.
Applying that argument to at and at gives
Adding these yields (3).
Finally, for , let .
Co-coercivity and the dual-norm Cauchy–Schwarz inequality give
If , divide by to obtain (1); if , (1) is immediate.
For the special case of the norm, we have:
Proposition 18
Let be a differentiable convex function with , and -smooth with respect to the Euclidean norm.
Then,
is monotone, i.e.
is convex.
If is twice differentiable, then,
When is both -smooth and -strongly convex, we have the following “strenghened” co-coercivity.
Proposition 19
Let have full effective domain and be -smooth and -strongly convex with respect to the Euclidean norm, where .
All norms in this proposition and its proof are Euclidean.
For any , we have
Proof
Consider the convex function .
Its gradient reads .
Using the -smoothness of , we have that
Since is convex on the full space, when its displayed upper inner-product bound implies the quadratic upper bound with parameter by Proposition 14.
The equivalence in Proposition 17 then shows that is -smooth.
The upper inner-product bound alone would not imply smoothness without convexity.
If , the inner-product bound for is both nonnegative and at most zero.
Its zero quadratic upper bound and convexity give for all , so is affine.
Consequently , and the claimed strengthened inequality holds with equality.
Otherwise, the -co-coercivity of (Proposition 16) gives us
Explicing the expression of allows us to conclude.
2.5 Exercises
Exercise 1
Prove that is convex if, and only if,
Exercise 2
Show that the following sets are convex.
The positive orthant: .
An hyperplane directed by : , for .
An half-space directed by : , for .
The unit-ball of a norm on : .
Exercise 3
Let be a differentiable function on an open set , and a convex subset of .
Prove that is strictly convex on if, and only if,
Bach, F. (2021). Learning Theory from First Principles. https://www.di.ens.fr/~fbach/ltfp_book.pdf
Baillon, J.-B., & Haddad, G. (1977). Quelques propriétés des opérateurs angle-bornés etn-cycliquement monotones. Israel J. Math., 26(2), 137–150. https://doi.org/10.1007/BF03007664
Evans, L. C. (1983). An Introduction to Mathematical Optimal Control Theory (p. 126). Department of Mathematics University of California, Berkeley.
Hiriart-Urruty, J.-B., & Lemarechal, C. (1996). Convex Analysis and Minimization Algorithms I: Fundamentals (Corrected edition). Springer.
Markowitz, H. (1952). Portfolio Selection. The Journal of Finance, 7(1), 77–91. https://doi.org/10.2307/2975974
Mohri, M., Rostamizadeh, A., & Talwalkar, A. (2012). Foundations of Machine Learning. The MIT Press.
Peyré, G., & Cuturi, M. (2018). Computational Optimal Transport. http://arxiv.org/abs/1803.00567
Recht, B. (2019). A Tour of Reinforcement Learning: The View from Continuous Control. Annual Review of Control, Robotics, and Autonomous Systems, 2, 253–279.
Rosenbrock, H. H. (1960). An Automatic Method for Finding the Greatest or Least Value of a Function. The Computer Journal, 3(3), 175–184. https://doi.org/10.1093/comjnl/3.3.175
Shalev-Shwartz, S., & Ben-David, S. (2014). Understanding Machine Learning: From Theory to Algorithms (1 edition). Cambridge University Press.
Vapnik, V., & Chervonenkis, A. (1974). Theory of Pattern Recognition. Nauka, Moscow.
Villani, C. (2009). Optimal Transport. https://link.springer.com/book/10.1007/978-3-540-71050-9