What's a Graph Neural Network?
Introduction to graph neural networks
There is a lot of expository materials on Graph Neural Networks (GNNs) out there. I want here to focus on a short “mathematical” introduction to it, in the sense to quickly arrive to the concept of equivariance and invariance to permutations, and how GNNs are designed to deal with it, in order to discuss in a future post our work (Keriven et al., 2020, 2021) on the convergence of GNNs to some “continuous” limit when the number of nodes goes to infinity.
1 Graphs
Graphs are ubiquitous structure 1 in mathematics and computer science.
Graphs may represent several interactions, such as brain connectivity, computer graphic meshes, protein interactions or social networks.
In its most elementary definition, a graph is a couple
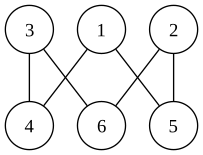
Beyond this formalism, it is quite frequent to enumerate the vertices
where
The graph in Figure 1 can be represented by the adjacency matrix
A popular way to encode it concretely on a computer is to use the so-called adjacency list, that we can represent mathematically speaking as a couple
The graph in Figure 1 can be represented by the adjacency list
We also say that a vertex
Note that when speaking about graphs, one might also think of more general structures such as
-
Digraphs (directed graphs) where
is not a subset of but a subset of ; -
Graphs with self-loop, i.e.,
; -
Multi/Hyper-graph where
might have repeated edges; -
or quivers, i.e., multi-digraphs, etc.
Another important generalization is the consideration of weighted (di)graph where instead of dealing with a couple
Note that we recover the standard definition of a unweighted graph if
2 Graphs in supervised learning
As a reminder, we typically say that we are performing supervised learning when we have access to a training set
where
where
2.1 Graph classification
Classification of graphs aims to answer questions such as “Does this protein
where
2.2 Node classification
In contrast, node classification aims to answer “Does this atom
where
Similarly to the Euclidean case, classification admits a continuous counterpart called regression, and one can define node regression as the task
Typical question would be “What is the energy
3 Invariance and Equivariance
In the context of graph learning, we are interested in the behavior of the function
3.1 Reminders on groups
A group is a couple
- Associativity.
For any
, one has
- Existence of a unit element.
There exists a unique element
such that for any , one has
- Existence of an inverse.
For any
, there exists a unique such that
Groups have a central place in the study of symmetry in algebra, and the notion of invariance emerges directly from it. Basic examples of groups includes
-
The real line endowed with the addition
; -
The set of rotations endowed with the composition
; -
The set of permutations endowed with the composition
.
3.2 Group action
Without diving in the subtilites of representation theory, we can recall that one of the most important tool of group theory is the notion of group action.
A (left) group action
-
associative: for all
, , one has ; -
identity law: for all
, one has .
A natural group action encountered in geometry and imaging is the (natural) action of the 2D (resp. 3D) rotations
Another well-known example is the action of
Remark that a group can act on different sets, for instance
These two examples of actions have a common property: they are linear group actions.
Linear group actions are probably the most fundamental examples of actions, and a whole field is dedicated to their studies: group representations.
A group action is said to be linear if
3.3 Invariance and Equivariance
Consider a function
For instance, if
Consider now a group
Important examples includes function that index-based in
4 A Fourier look at graph signal processing
At this point, we are quite far from concrete application in machine learning. A first question is: what are the invariance or equivariance that we want to enforce? In the following section, we will consider the important example of shift-invariance as a building block of Convolutional Neural Networks.
4.1 Convolution
The convolution is a fundamental operation in signal processing.
Given two real functions
One may look at
For our purpose, the important property of convolution is that it is shift-equivariant.
This means that if we shift the input signal, the output signal is shifted in the same way: if
where
In traditional signal processing, such filters
Our issues here are
-
What is a convolution on a graph?
-
Even more basic, what is shift-equivariance on a graph?
There is no universal answer to these two questions.
4.2 Convolution and Fourier
For an integrable function
On the
The key property used in signal processing is that Fourier transform diagonalize the convolution: for any
I show in Figure 2 an example of the convolution of two functions and its Fourier transform.
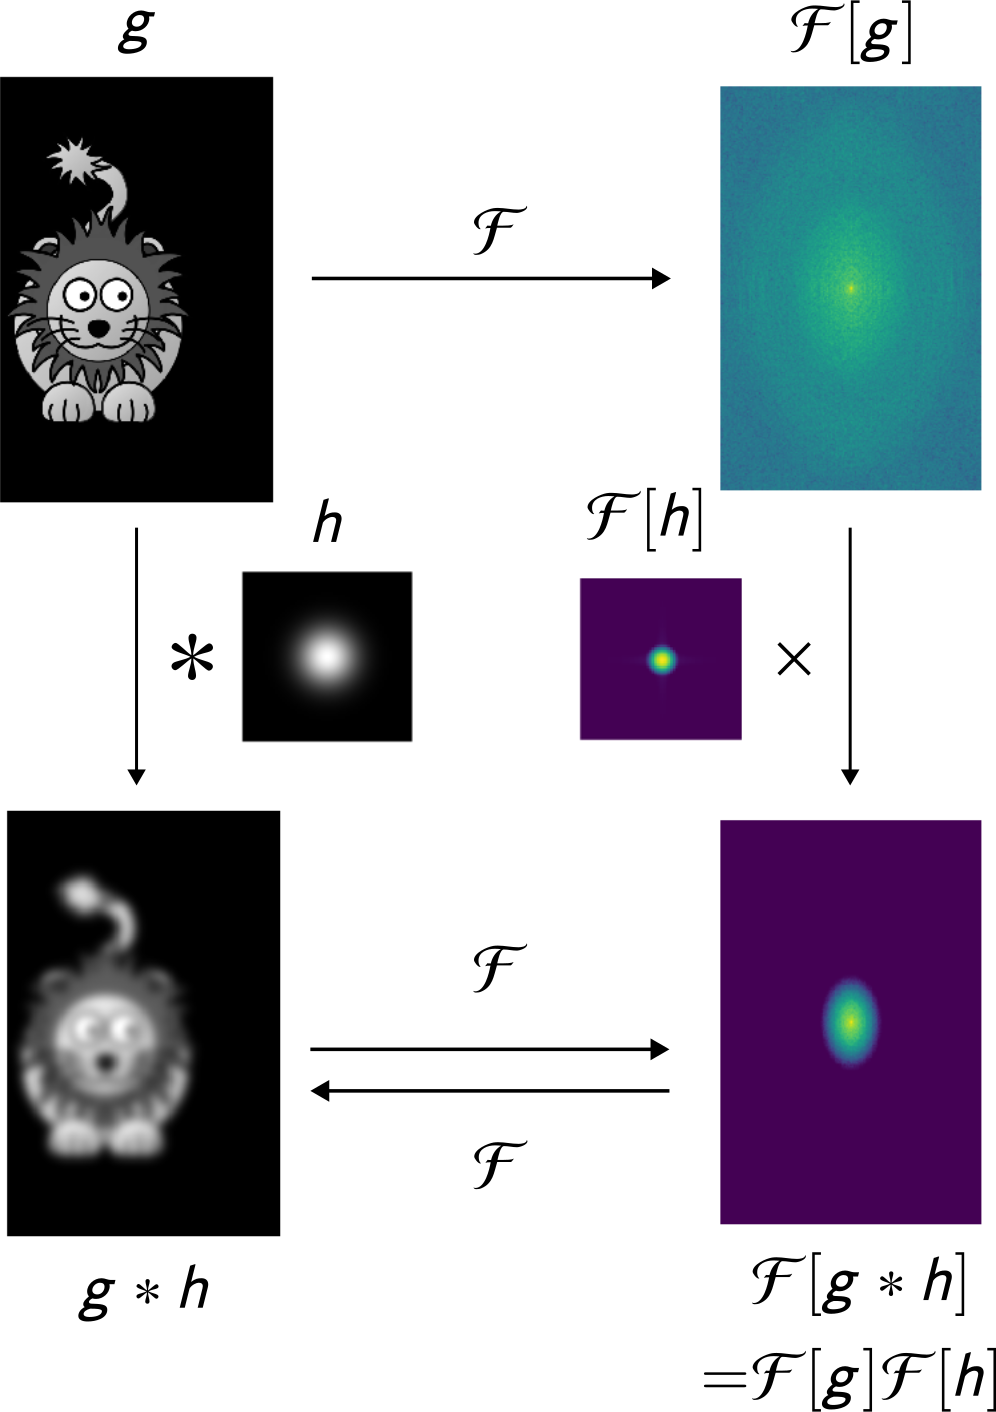
The goal hence is to define what is a “Fourier transform” on graphs.
To this end, we take yet another interpretation: the complex exponentials
5 Graph Laplacian
Definition 1
Graph Laplacians The (combinatorial) graph Laplacian of a graph
where
The (normalized) graph Laplacian of a graph
The combinatorial graph Laplacian is a semidefinite positive symmetric matrix associated to the quadratic form
The spectral graph theory is more often concerned with the normalized version (Chung, 1997). It has several interesting properties (among many others):
Proposition 2
Let
-
is a differential operator on the space of function : -
There exists a matrix
such that and is called the normalized incidence matrix that reads -
is a real symmetric operator.
An other important fact is that seeing
5.1 Graph Fourier Transform
The last point of Proposition prp-laplacian-graph, namely the fact that
Observe that
Recall that the Fourier transform on
where
Definition 3
Let
We can rewrite it in matrix form as
5.2 Filtering on graphs
Given the definition of the GFT, how to filter a signal?
The idea is to act on the eigenvalues of the eigendecomposition, and let eigenvectors untouched.
So given a filter
where
In practice, diagonalizing the Laplacian is too costly.
What people use is polynomial, or analytical, filters of the Laplacian.
Given a polynomial, or formal serie,
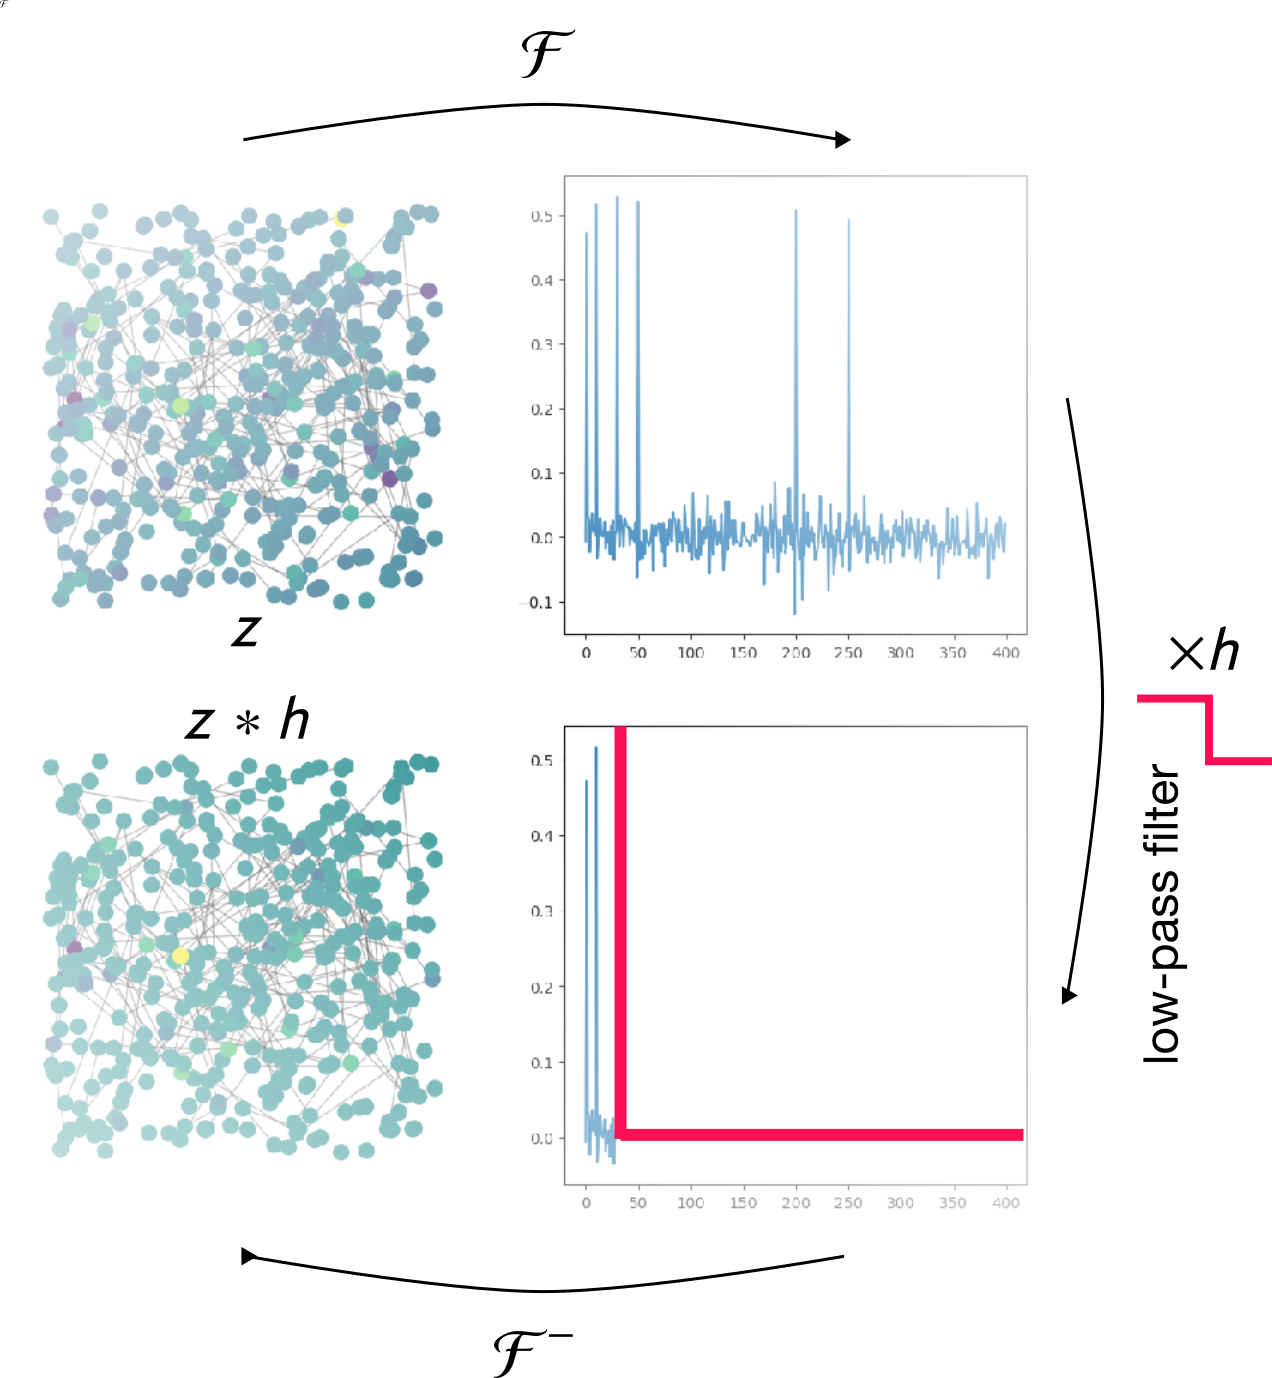
Note that from a theoretical perspect, it is still only application on the eigenvalues. Figure fig-conv-graph illustrates the filtering of a graph signal by a low-pass filter.
6 Graph Neural Network
6.1 (Spectral) Graph Convolutional Network
Up to some subtles or notational differences, you probably encounter CNNs as parametric function defined layer-wise by a combination of
-
non-linearities such as ReLU;
-
convolution layers mapping a tensor to another;
-
pooling (or subsampling) reducing the dimension using for instance a max- or mean-pooling;
-
fully connected layers (Multi-Layer Perceptron, MLP) to produce an output.
In the context of GNNs, non-linearities will be the same (typically Lipschitz function different from the identity), convolution will be used as defined in the previous section, MLPs will be the same. But what about pooling? This is (mostly) an open question in the GNNs on how to produce good and efficient pooling operation, also known as graph coarsening. These architectures were defined around 2015, by Henaff et al. (2015) and Defferrard et al. (2016).
A GCN with
-
The signal at the input layer is some node features
with dimension and built up columns . -
For all
, the signal at layer is obtained by propagation of the signal at layer with respect to analytic filters of the normalized Laplacian: -
The output depends on the notion of invariance that one wishes to preserve.
-
-equivariance (node classification). In this case, the output of the GCN is a node-signal defined as where
is a MLP applied row-wise to the signal . -
-invariance (graph classification). In this case, the output is a single vector given as a global pooling
-
6.2 Invariance and Equivariance of GCNs
In the definition of GCNs, it was roughly said that we can made the output either
where we defined the action on the graph and the signal as
The action on the group is more easily defined in fact on the adjacency matrix.
For any
Cutting the algebraic details, these two definitions are perfectly equivalent.
We can now state the result
Proposition 4
For any
Proof
See for instance Proposition 1 of Keriven et al. (2020).
The proof of
-
The map
is -equivariant; -
Hence the map
is -equivariant; -
Permutations matrices commutes pointwise with entrywise activation function.
To get the
7 Another paradigm: Message-Passing Graph Neural Networks
Before ending this nose, let me mention that around 2017, Gilmer et al. (2017) and Kipf & Welling (2017) proposed a new architecture, or at least a new interpretation, that “forget” the spectral interpretation of GCNs. It is closer in the spirit to original graph neural network model, and is now the standard way to think of GNNs. I still believe that the spectral interpretation highlights important properties of GNNs, and is a good way to understand the behavior of GNNs.
Instead of a spectral interpretation, a neighborhood aggregation, or so-called message-passing architecture is proposed:
where
-
is the node feature at layer of node ; -
(the update function) and (the message-passing function) are learnable functions such as traditional MLPs; -
is an agregation function such as sum or maximum ; -
is a (potential) edge features.
In many papers, this is presented in the equivalent form (often with multisets for the aggregation)
Let me mention several important examples of MPGNNs:
-
Convolutional GNN. Wait what, didn’t we called them spectral GNNs? Yes, but we can look at them in a slightly more general way
In practice, the community consider a more constrained version:
where
is a learnable matrix. This can be even more precisely specified (in matrix form) as or in normalized form as
-
Attentional GNN.
where
is a learnable self-attention function.
Without diving into the details, I want to attract your attention that when dealing with a graph with only self-loop, or when
-
When
– so not a classical graph, you have to add a self-loop – the convolutional architecture boils down to the Deep Sets architecture (Zaheer et al., 2017). -
On the other extreme, when
for all (again with self-loop), the attentional GNN is linked to the Transformer (Vaswani et al., 2017) architecture.