A short introduction to automatic differentiation
Lecture notes, Optimization for Data Sciences
· · #optimization #automatic-differentiation · PDF · Markdown
1 Introduction
Automatic differentiation libraries include, in Python, PyTorch, JAX and TensorFlow, and in Julia, Zygote, among others. They have been used in machine learning since roughly 2005–2010. The underlying ideas come from optimal control: Lions in the 1970s–1980s, then A. Walther, A. Griewank and others in the 1990s.
Automatic differentiation, as the name implies it, is a differentiation method.
Given a smooth function
1.1 Cheap Gradient Principle
Before diving into the core material, let us mention the cheap gradient principle from Baur–Strassen.
Let
Complexity.
Here
Theorem 1: Baur–Strassen
For
Backpropagation is exactly taking advantage of these “theoretical” result, preserving more or less the small constant in front of
1.2 Finite Differences
Apart from computing by hand if the analytical expression is known, a common way to approximate a derivative is to use a finite difference scheme.
Let
which suggests the approximation
The error decomposes into a round-off part and a truncation part of order
where
So why bother doing something else? There are at least three reasons:
-
Computing a full gradient or Jacobian by forward differences takes one function evaluation per input coordinate, plus a shared evaluation at the base point.
-
It is highly sensitive to the choice
. -
Subtracting nearly equal values can amplify floating-point error when the step is small.
It is possible to improve the finite difference used above (called the forward finite difference) by using centered difference.
Basically, it replaces the estimate
1.3 Complex Step Approximation
Can we avoid this nasty round-off error?
Let
Taking real and imaginary parts,
hence with truncation error
Unlike finite differences, this involves no subtraction of nearby quantities, so it avoids subtractive cancellation, although floating-point round-off is still present. One of the issue is you need to have a stable complex arithmetic to be able to use this trick.
2 Forward differentiation over scalar functions
2.1 Dual Numbers
The complex-step method avoids subtractive cancellation.
Can we now avoid the truncation error?
It looks impossible, right?
We would like a “number”
holds exactly, with no remainder.
The key idea is is to introduce
-
as
completed by an element such that ; -
as the set
endowed with a specific law ; -
or as the quotient
.
Concretely,
Observe that essentially, going from
2.2 Linearize everything
So, can we linearize errors with this ring?
Polynomials linearize: for
What kind of sorcery is behind this?
Extending this analysis to analytical function (over an open set of
2.3 Forward-Mode Automatic Differentiation
It turns out that dual number represents one “mode” of automatic differentiation.
For
and it works for composition:
Remark 2
In Python one implements a class Dual carrying self.real and self.dual, overloading __mul__ and __add__ to encode the rules above.
In Julia the same behaviour is obtained through multiple dispatch.
We call that operator overloading.
Other possibilities include record tape, the original one by Wengert and used for instance by the eager mode of PyTorch, and source-to-source transformation (e.g., Tapenade for FORTRAN code).
3 Reminders on functions of several variables
We now recall basic definition of calculus of several variables, mainly as a pretex to define vector-Jacobian and Jacobian-vector products.
3.1 Gradient
For
A forward-difference approximation of the full gradient uses
3.2 Directional derivative
Here our function is from
which needs only
3.3 Jacobian
For
For forward finite differences, the full Jacobian uses
4 Chain Rule
Let
-
If
, then . -
If
and , then
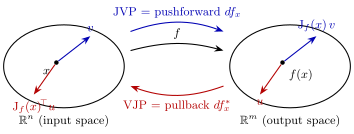
5 JVP versus VJP
JVP (Jacobian–vector product).
The finite-difference approximation uses two evaluations of
VJP (vector–Jacobian product).
For
The dual part jvp/vjp):
6 Computational Graph
The key point to understand automatic differentiation is to view computer programs as evaluation of a computational graph.
A computational graph represents the stack of evaluation performed by the program.
Consider

The intermediate variables are
By the chain rule,
Writing
6.1 Forward mode
Since
For
-
Input:
-
-
-
for
do -
-
return
and
6.2 Reverse mode (backpropagation)
Since
with cost
For
Reverse mode stores the intermediate values needed by the backward pass, using memory proportional to the total size of those stored values. Forward mode can stream through a chain, retaining only the current primal and tangent states. Checkpointing is a way to alleviate this issue.
-
Input:
-
, ( ) -
for
do -
for
to do -
return
and ( )
7 Backpropagation on a General Graph
The graph above was a chain: every node had exactly one predecessor, so the Jacobian factorised as a single sequential product.
A real program is not a chain but a directed acyclic graph (DAG): a variable may feed several operations (fan-out) and an operation may read several variables (fan-in).
The running example
The graph.
Write
where
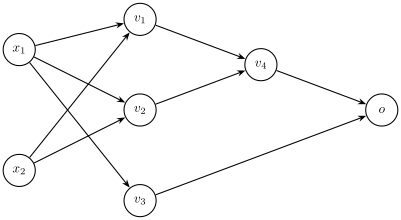
+ - * /, ^, exp/sin/cos/log/sqrt/tanh). Above each node: value (forward). Below, in bold: adjoint ∂o/∂· (reverse).with
Topological order.
A topological order is a linear ordering
The chain rule with fan-out.
Let the adjoint of
This sum is the entire difference with the chain case.
When every node has a single child the sum has one term and we recover the sequential product
Reverse sweep.
Seed
-
Input: DAG
with inputs and sink -
topologically sort
as (sources first) -
Assign the given input values to the source nodes
-
for
do -
if
is not a source then (store )
-
-
for all , -
for
do -
for each
do - $\bar{x}_u \leftarrow \bar{x}_u
- \big(\partial \phi_{v_t} / \partial x_u\big)^\top \bar{x}_{v_t}$
- $\bar{x}_u \leftarrow \bar{x}_u
-
-
return
The example, backward.
The reverse sweep gives
which is exactly
Cost.
Each edge is traversed once per pass, so the backward sweep costs a constant times the forward graph, the cheap-gradient principle on an arbitrary DAG, at the price of storing the intermediates